

The AI reliability platform for
proactive cloud operations
Engineered for the world’s most demanding architectures

OccamsHub platform
Automates reliability workflows with specialized Copilots trained on real-time context from high-cardinality telemetry and tribal knowledge
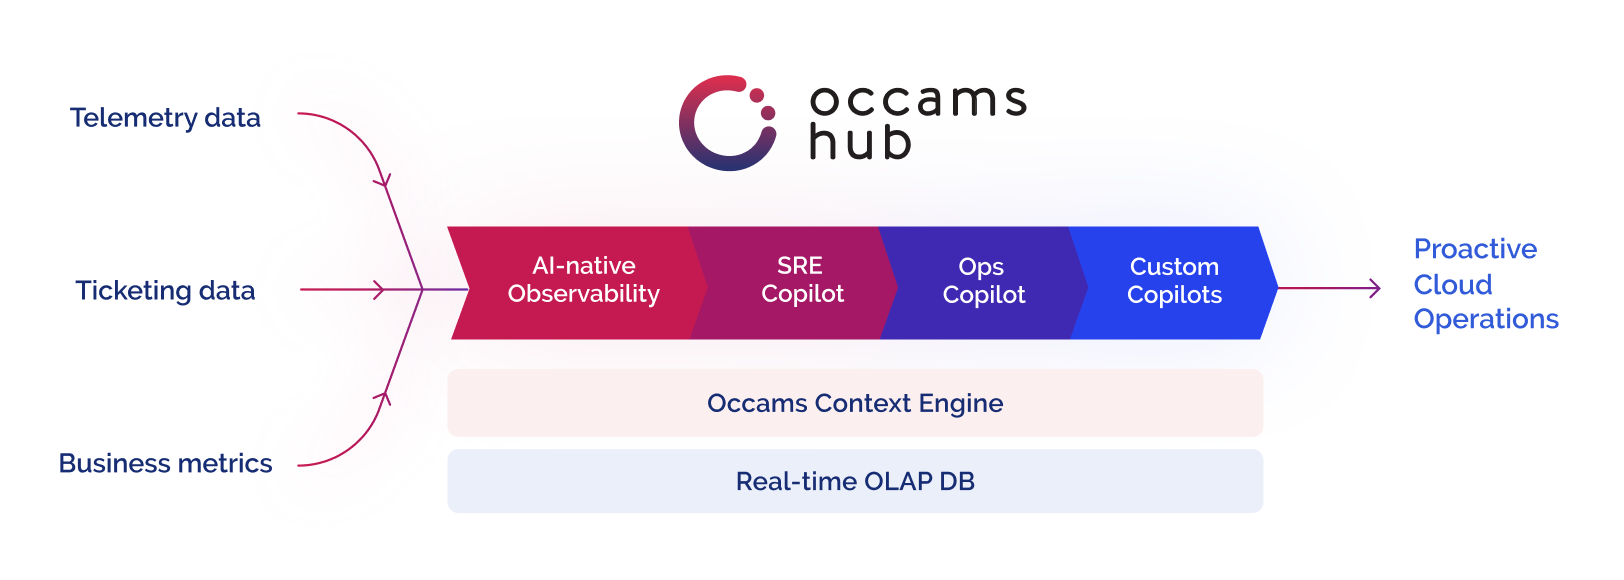
Occams Context Engine
The real-time, stateful “digital twin” of your distributed system.
It fuses live telemetry, failure simulations, and human feedback into a multi-dimensional context graph. This gives our copilots the deterministic environment model required to prevent AI hallucinations.
Multi-dimensional context graph
Transforms real-time telemetry into stateful operational context.
- Topological dependency and failure mapping
Dynamically maps service topologies, traces failure propagation paths across microservices, and maintains system state in real time. - Performance simulations
Runs simulations to model end-to-end journey performance under synthetic latency, component degradation, or failure conditions. - Closed-loop domain learning
Captures engineer validations to continuously train models on your specific architecture.
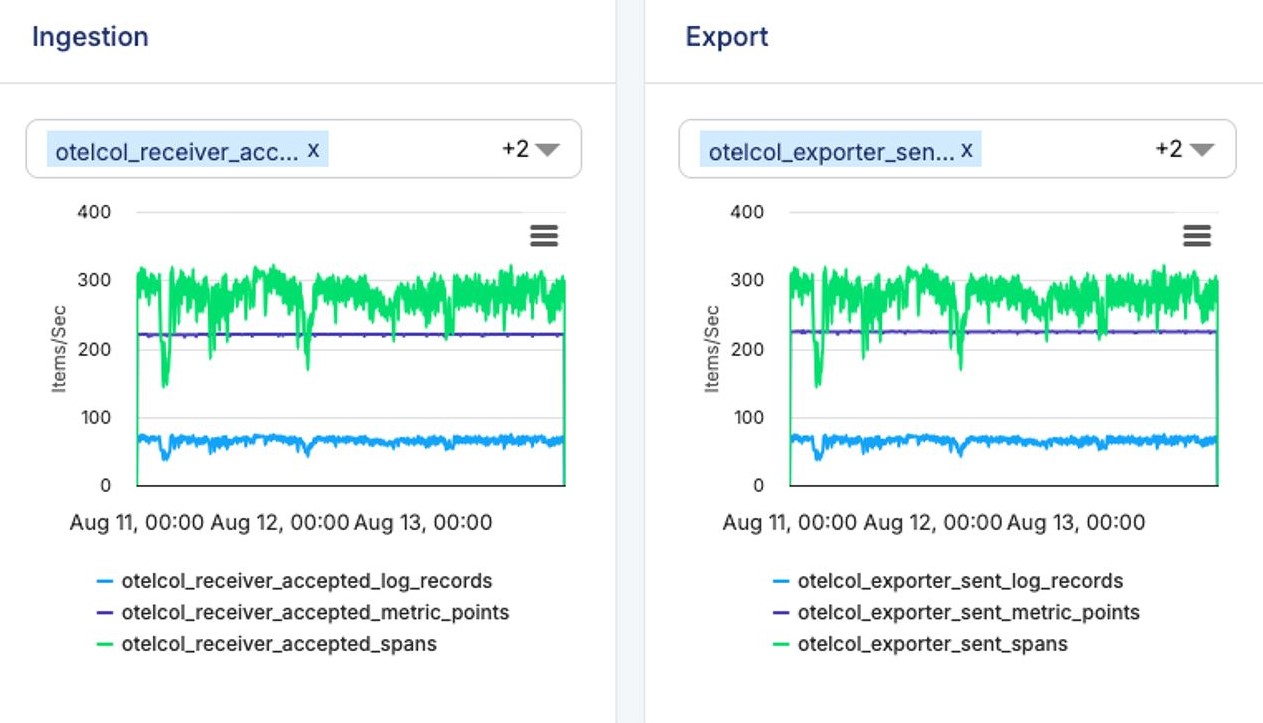
High-throughput streaming and OLAP Core
The real-time data engine powering the Occams Context Engine.
- Real-time entity discovery
Discovers system entities and maps their dynamic relationships instantly as telemetry streams through the pipeline. - Stateful statistical modeling
Computes real-time streaming analytics across complex distributed entities while maintaining stateful statistical correlations. - Automated stream correlation
Performs fuzzy string matching across high-velocity log streams to identify and track evolving cross-service dependencies in real time.
AI reasoning engine
Context-aware orchestration and narrative synthesis.
- Deterministically anchored RCA
Translates pre-correlated context objects into human-readable root cause narratives backed by auditable trace links and metric attribution. - Guided playbooks
Maps live incident context to recommend step-by-step diagnostic workflows. - Token efficiency
Operates over pre-structured context objects rather than raw log dumps, reducing LLM token consumption and API latency by over 90%.
Enterprise security & governance guardrails
Trust-first AI architecture engineered for strict enterprise compliance.
- Zero LLM data retention
Raw telemetry and proprietary system context remain 100% private and within isolated tenant boundaries. Your operational data is never used to train public foundational models. - Strict read-only guardrails
Copilots operate as diagnostic and analytical assistants with zero production write risk and full Role-Based Access Control (RBAC). - Enterprise compliant
SOC 2 Type II compliant architecture built to satisfy strict corporate governance and regulatory requirements.
Why context matters
You cannot feed millions of logs into an LLM without it hallucinating and overrunning budgets. OccamsHub Context Engine decouples heavy quantitative modeling from the LLM reasoning layer, preventing hallucinations and allowing our Copilots to build trust with engineers.
SRE Copilot
Production failure shouldn’t be your first alert.
SRE Copilot acts as an automated reliability engineer embedded in your stack. It continuously reasons across service topologies, tracks journeys, detects architecture drift, enforces error budget health, and predicts cascading failures before end users are impacted.
Automated SLOs
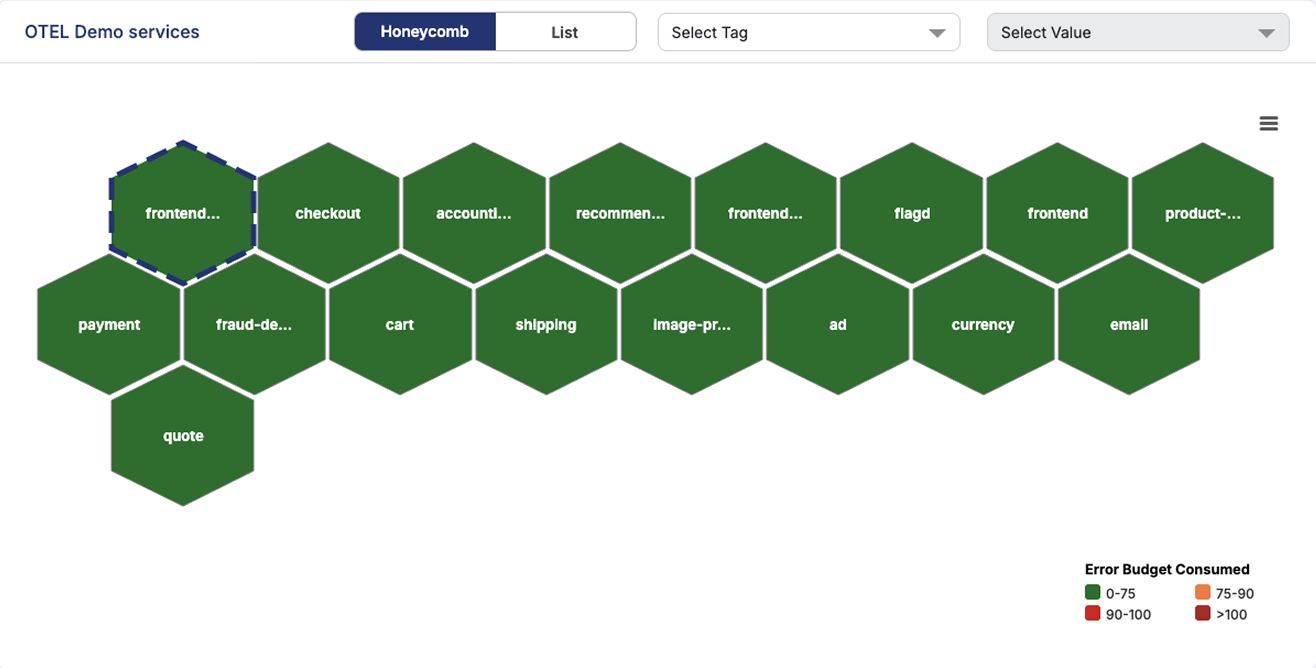
Skip dashboard building and manual threshold tuning with zero-config SLOs.
- Zero-config error budgets
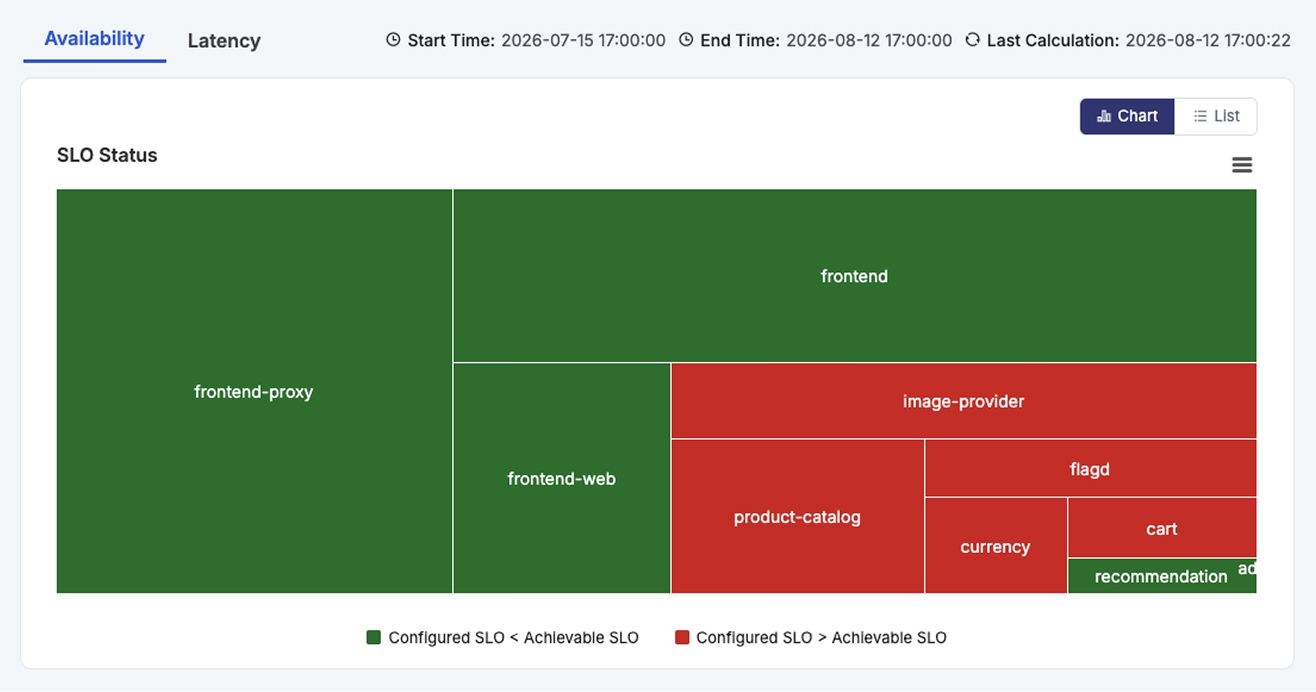
Automatically derives dynamic Service Level Objectives (SLOs) and error budgets by accounting for all service dependencies and running performance simulations. This eliminates manual endpoint configuration and threshold tuning entirely. - Architectural drift detection
Automatically detects architectural drift across evolving microservices and triggers automated SLO update workflows to keep reliability targets aligned with production reality. - Multi-window burn velocity alerting
Monitors journey error budget burn velocity in real time, triggering multi-window multi-burn-rate alerts before a critical path breaches its SLA.
Zero-touch topology mapping
Get total visibility into your architecture without writing a single line of config.
- Automatic discovery
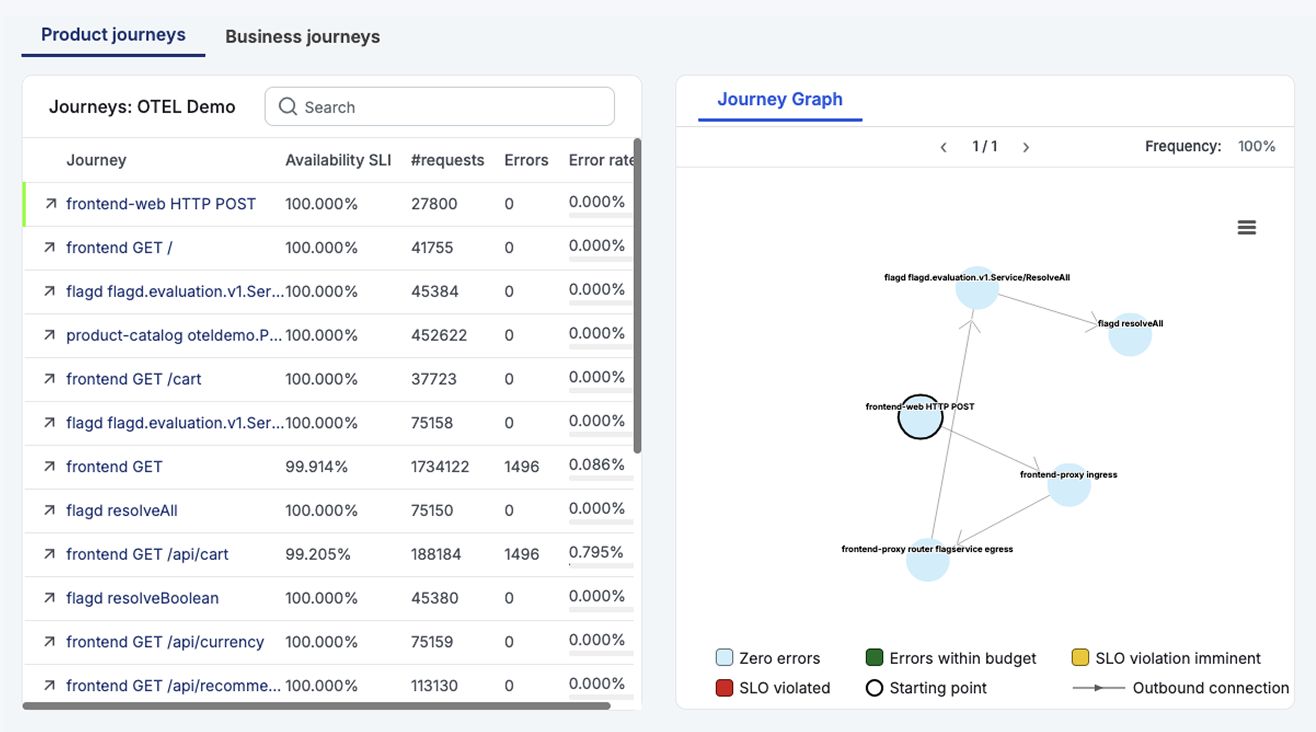
Ingests OpenTelemetry semantic conventions out of the box to dynamically map service dependencies, database connections, and API boundaries. - Tracking product journeys
Automatically analyzes distributed trace flows and logs into journeys (e.g. checkout_flow, identity_auth). - Performance bottleneck discovery
Navigates topological dependencies in real time to isolate performance bottlenecks across endpoints, underlying services, and critical journeys.
Outage forecasting
Fix performance degradation before it turns into a P1 fire drill.
- High-cardinality anomaly detection
Scans raw telemetry for subtle micro-anomalies across dynamic tags (k8s_pod, customer_tier, region) long before static global thresholds breach. - Pre-outage issue detection
Continuously forecasts performance signals across cascading dependencies, proactively flagging service degradation issues before they cause an outage. - Proactive prevention guardrails
Recommends architectural adjustments and capacity tweaks before error budgets burn out.
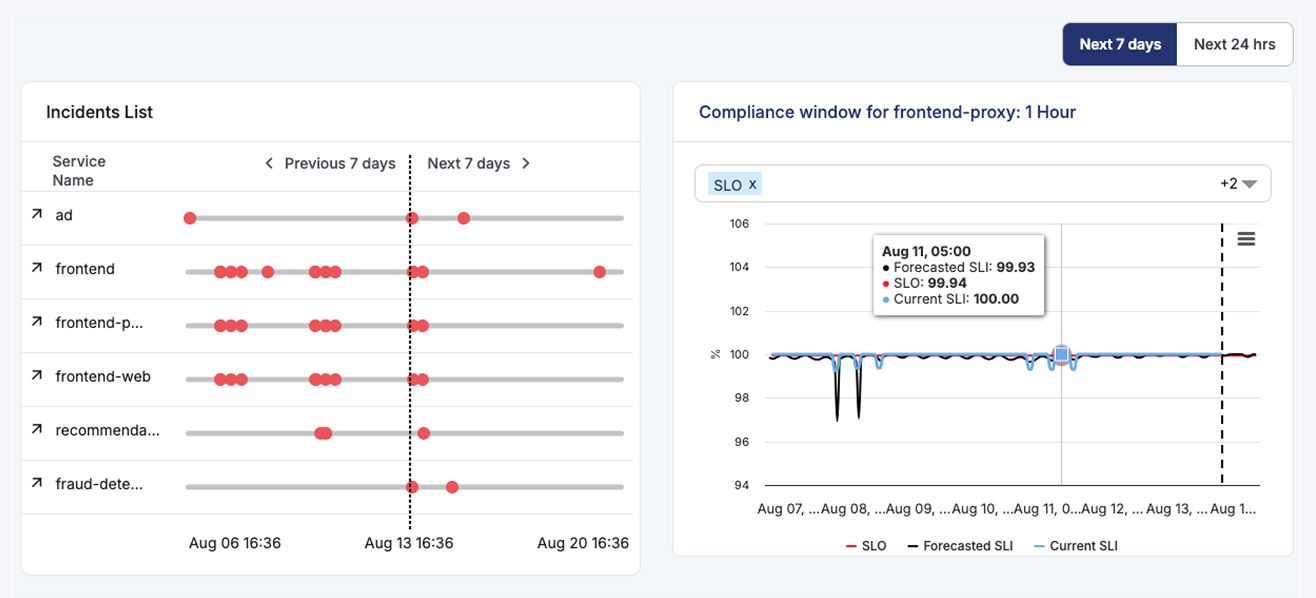
Drive reliability as a feature
Legacy APMs force engineers to spend weeks building static dashboards and tuning threshold alerts that only trigger after an outage begins. SRE Copilot leverages native OTel streams to automatically map your system, baseline SLOs, and predict failures before your customers ever notice.
Ops Copilot
Eliminate P1 fire drills
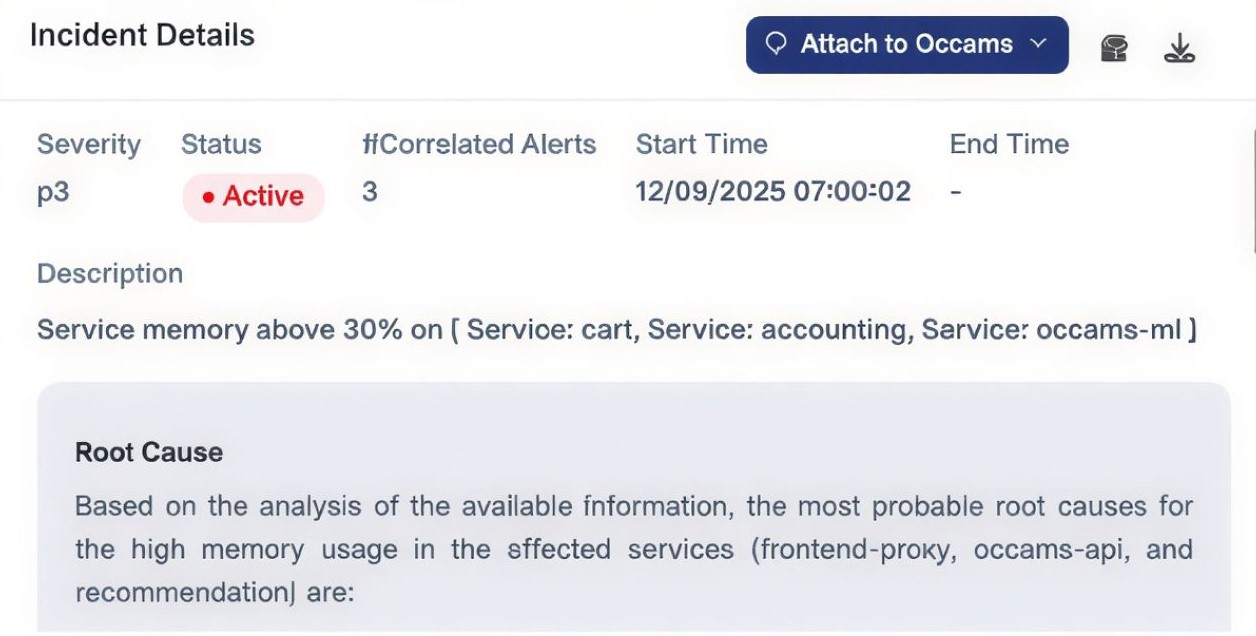
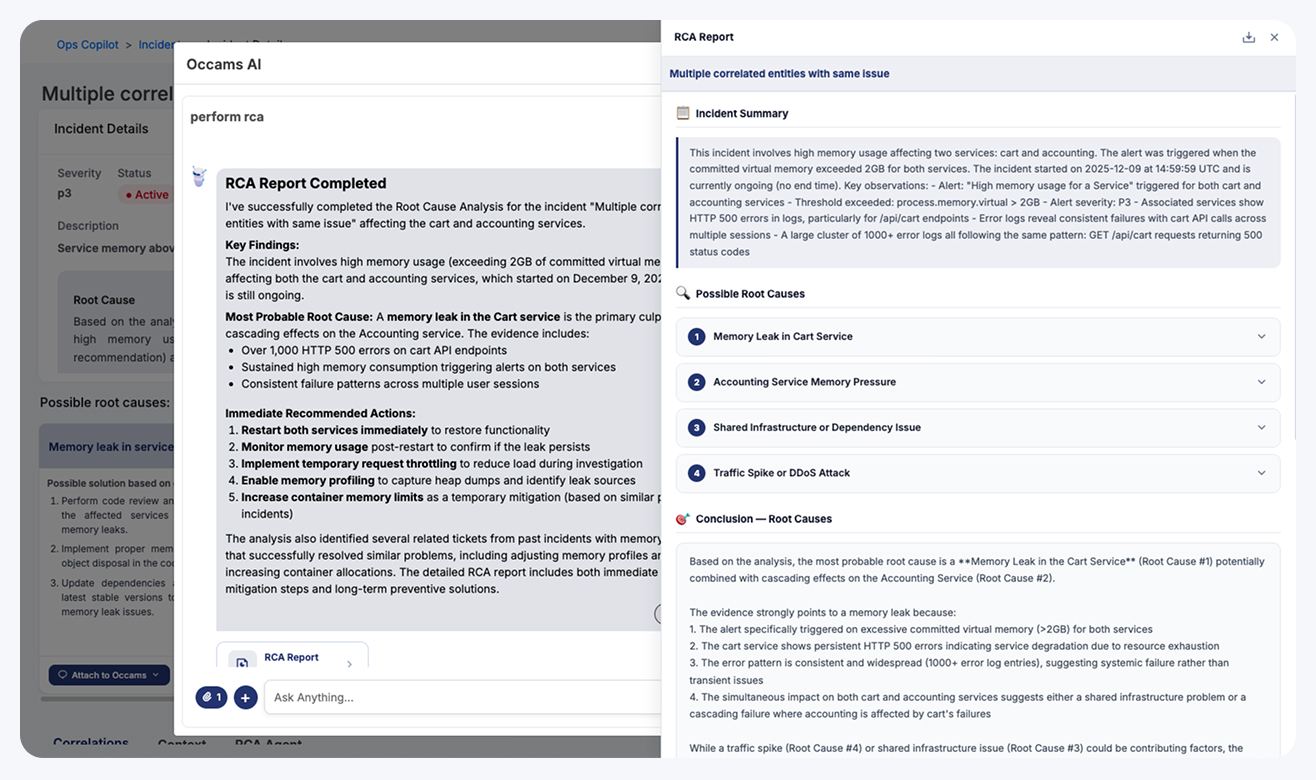
Ops Copilot acts as an automated incident responder embedded in your stack. It continuously correlates telemetry in real time, isolates the exact root cause in seconds, and delivers deterministic execution plans so your team recovers instantly.
Automatic root cause analysis (RCA)
Pinpoint the exact code commit or infrastructure shift causing the outage.
- Automated context-aware triage
Analyzes incidents in seconds by cross-referencing golden signals, statistical correlations, anomalies, and live telemetry with recent code commits, feature flags, and infrastructure deployments to surface immediate root cause insights. - Automated blast-radius analysis
Performs drill-downs across high-cardinality dynamic tags—filtering by container_id, customer_tier, or region to surface immediate blast-radius insights. - Noise suppression & deduplication
Consolidates hundreds of cascading alerts across microservices into a single, cohesive incident timeline, reducing alert fatigue.
Human-in-the-loop remediation
Get immediate, evidence-backed diagnostic answers without chasing red herrings.
- Actionable remediation guidance
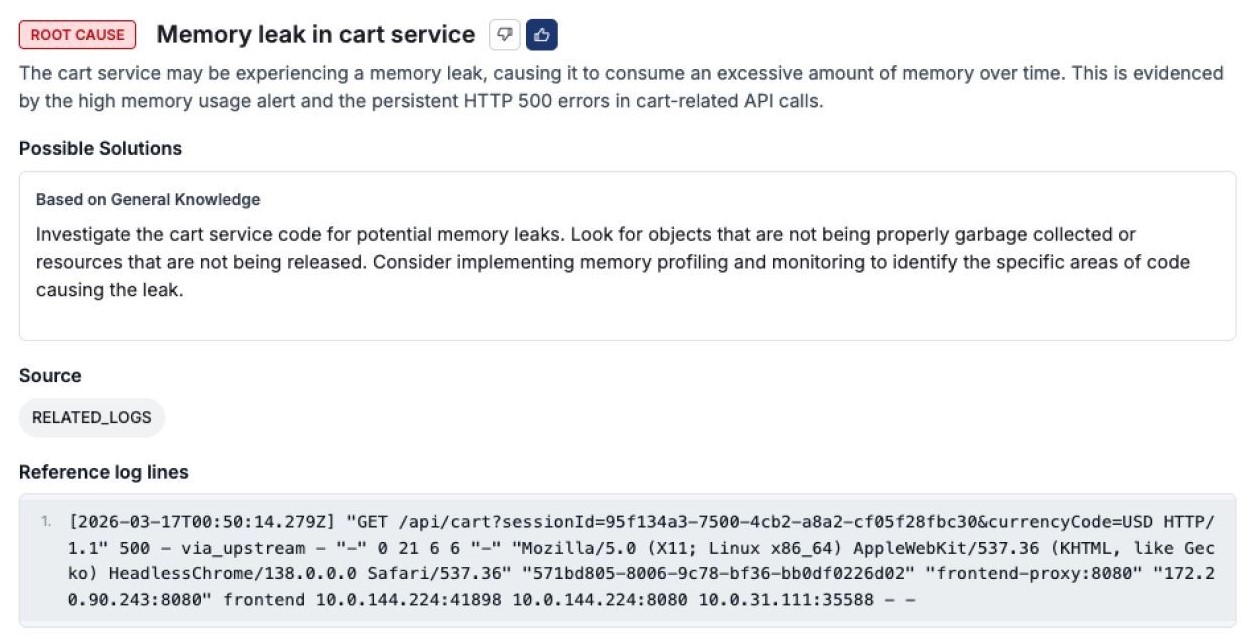
Generates step-by-step, precise fix recommendations—giving engineers the exact context needed to resolve issues quickly. - Auditable attribution
Provides transparent, verifiable reasoning alongside every diagnosis, surfacing the exact log snippets, trace paths, and metric anomalies that led to the conclusion. - Seamless workflow integration
Surfaces diagnostic summaries and recommended action plans directly in your incident response tools where your engineers already collaborate.
Systematize tribal knowledge
Turn chaotic firefighting into repeatable institutional intelligence.
- Automated post-mortem generation
Instantly compiles comprehensive, accurate incident summaries—including timeline, root cause, blast radius, and recovery actions. - Tribal knowledge ingestion
Learns from historical incident resolutions and runbooks to continuously improve future correlations and root-cause recommendations. - Escalation path reduction
Eliminates cross-team war rooms by providing engineers with instant, clear context across every layer of the stack.
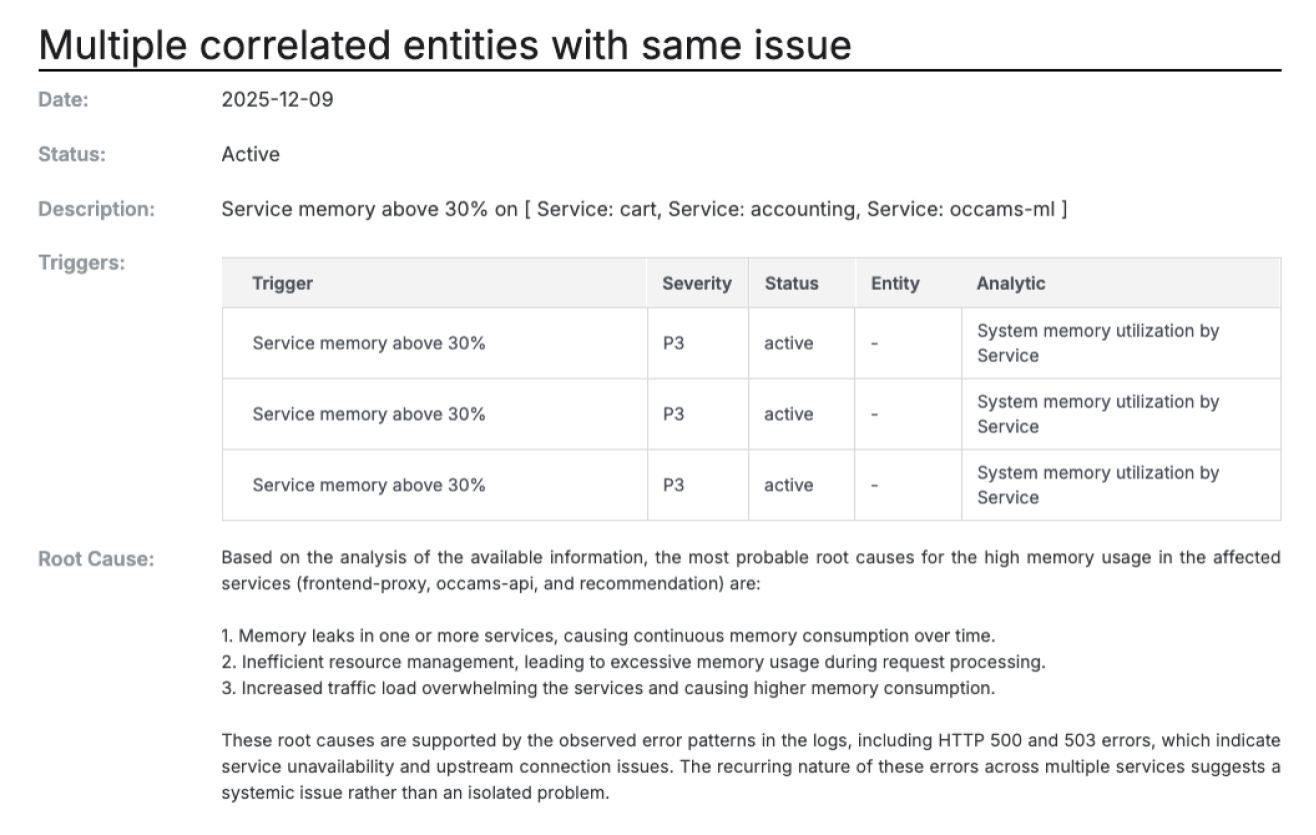
Prevent hallucinations in your RCA
Generic AI SRE agents guess what went wrong based on text summaries. Ops Copilot queries raw, high-cardinality telemetry in real time, delivering deterministic proof and actionable remediation before your SLA burns out.
Custom Copilots
Your domain context. Your operational rules. Grounded intelligence.
Custom Copilots allow platform teams to encode proprietary business logic, custom correlations, and team workflows directly into the Occams Context Engine. This enables custom automation across FinOps cost planning, multi-tenant isolation, and policy enforcement.
Define proprietary context
Ground AI in your unique architecture, business logic, and internal metadata.
- Custom entity mapping
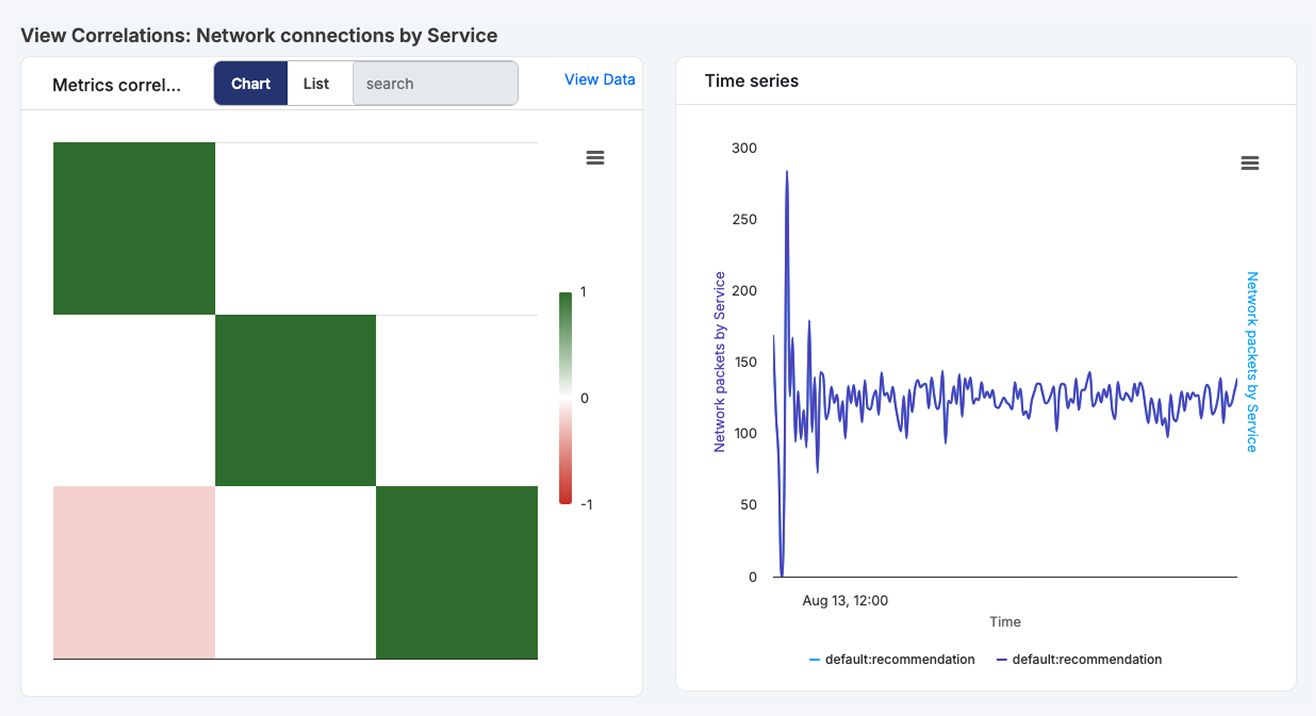
Binds infra tags, cost center tags, deployment metadata, and vendor SLA terms directly to live OpenTelemetry streams.. - Custom correlation rules
Allows platform teams to define proprietary relationships across domain-specific metrics, logs, and business events. - Streaming analytics & ML models
Computes real-time statistical correlations across streaming analytics views and feeds cross-service dependency math directly into AI context windows.
.
Specialized domain intelligence
Address non-standard operational challenges, from cost engineering to multi-tenant isolation.
- Real-time cost engineering
Continuously evaluates live OTel streams against historical cost baselines to flag unexpected burn-rate spikes. - Noisy-neighbor mitigation
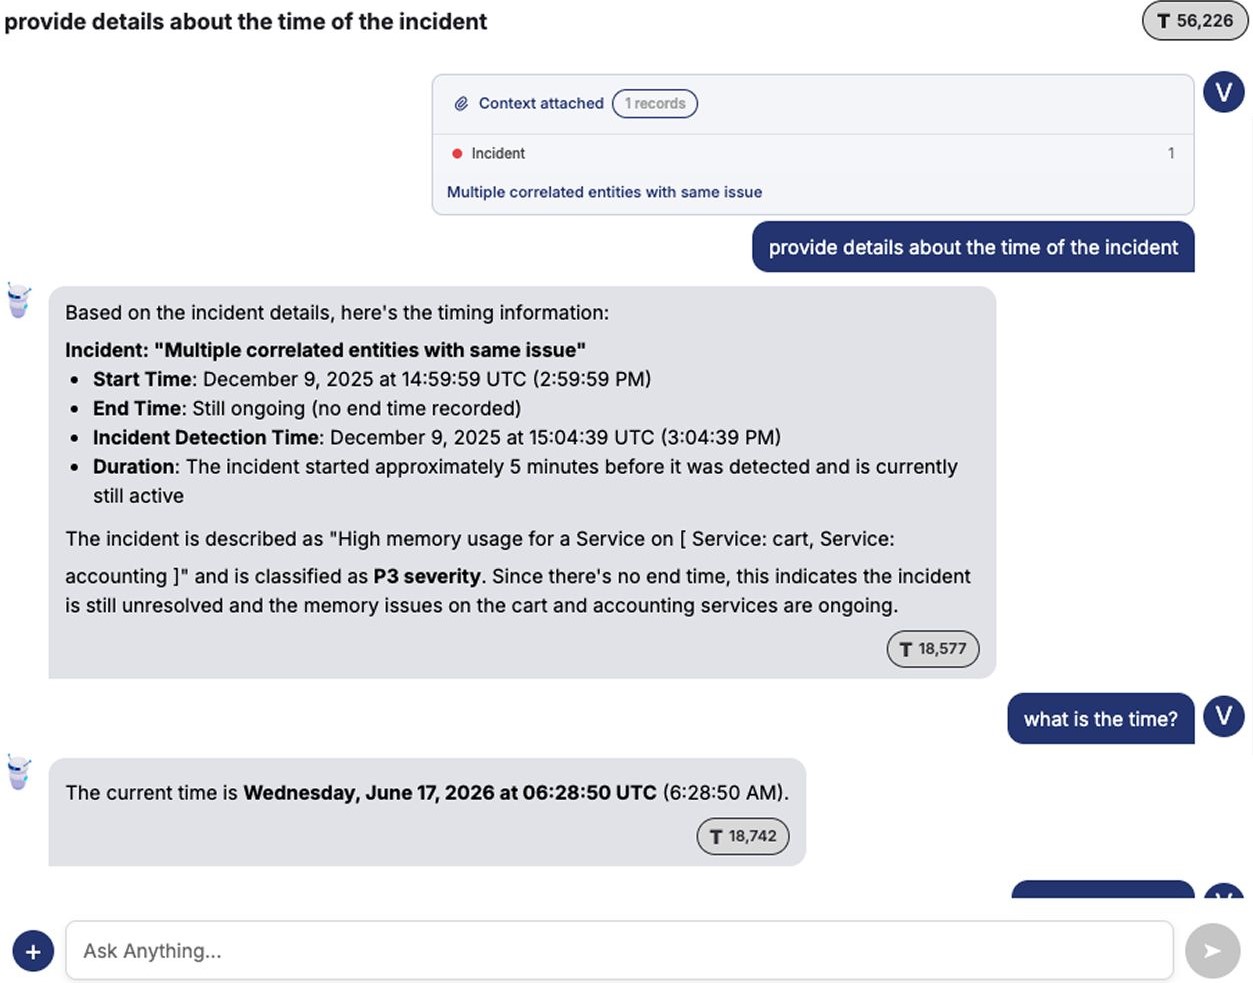
Detects when specific customer tiers degrade shared cluster resources and triggers targeted isolation runbooks. - Domain-aware investigative Q&A
Enables engineers to ask complex questions about system state, failure modes, and past incident patterns with zero risk to production.
.
Open MCP server
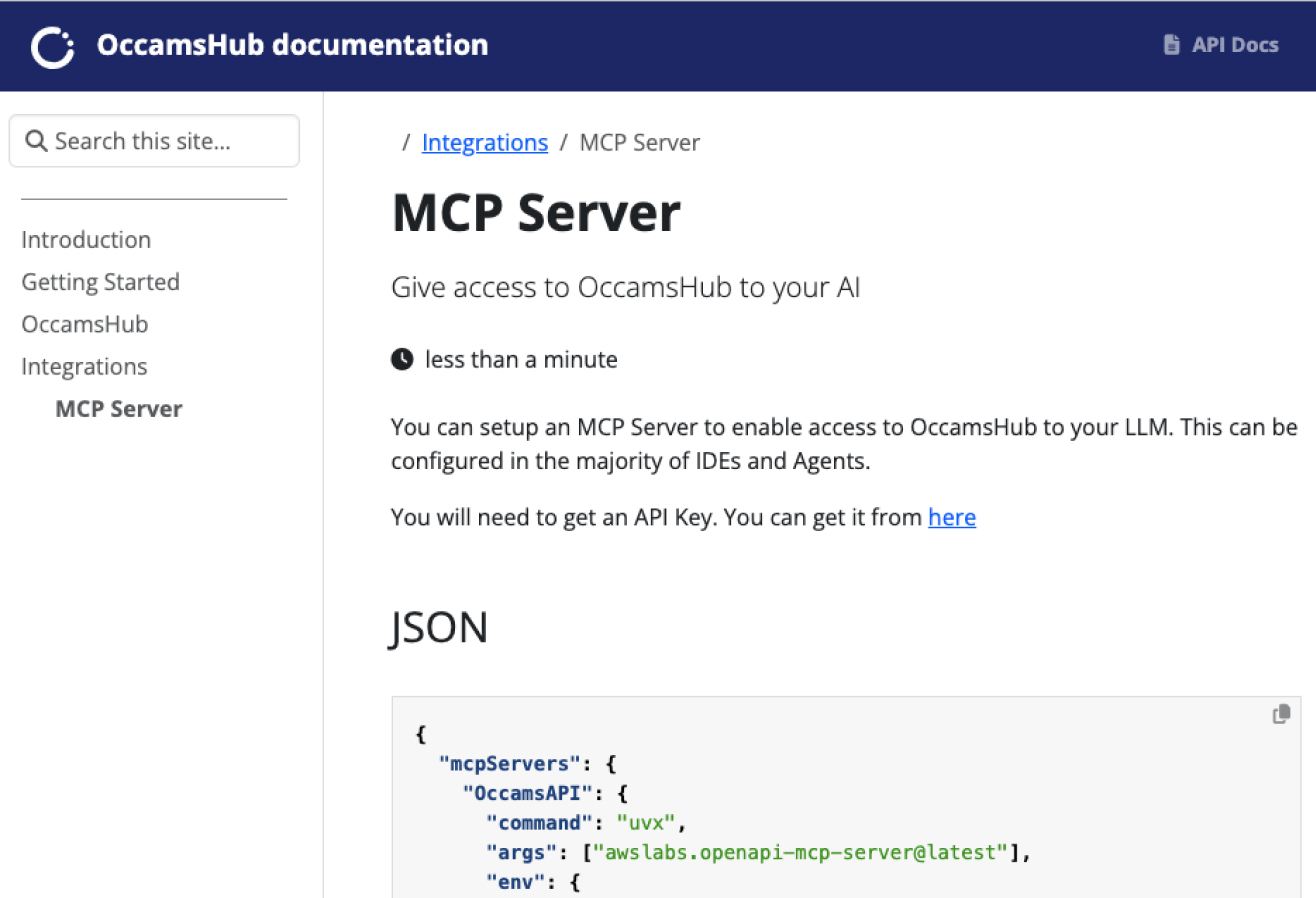
- Native Model Context Protocol (MCP)
Serve real-time telemetry, statistical matrices, and context graphs directly to external developer tools, Cursor IDEs, Claude Code, or internal Slack bots. - Event-driven trigger loops
Automatically initiate custom diagnostic investigations via triggers, or custom alert engines. - Immutable auditability
Maintain complete enterprise compliance with full audit logs tracking every context query, historical document retrieval, and diagnostic answer.
Grounded copilots, not unguided agent loops
Custom Copilots aren’t open-ended LLMs guessing which tools to call. Grounded in the Occams Context Engine, they execute bounded, deterministic operational workflows in seconds. This eliminates the latency, hallucinations, and token cost of generic agent loops.
AI-native Observability
Full-stack visibility. Eliminate cardinality tax.
Stop paying millions just to store log noise. OccamsHub embeds native OpenTelemetry ingestion directly into the AI runtime layer. This unifies metrics, logs, and traces while slashing legacy APM bills by up to 60% through columnar OLAP storage efficiency.
Correlations at scale
Stop hopping between disconnected dashboards during an active incident.
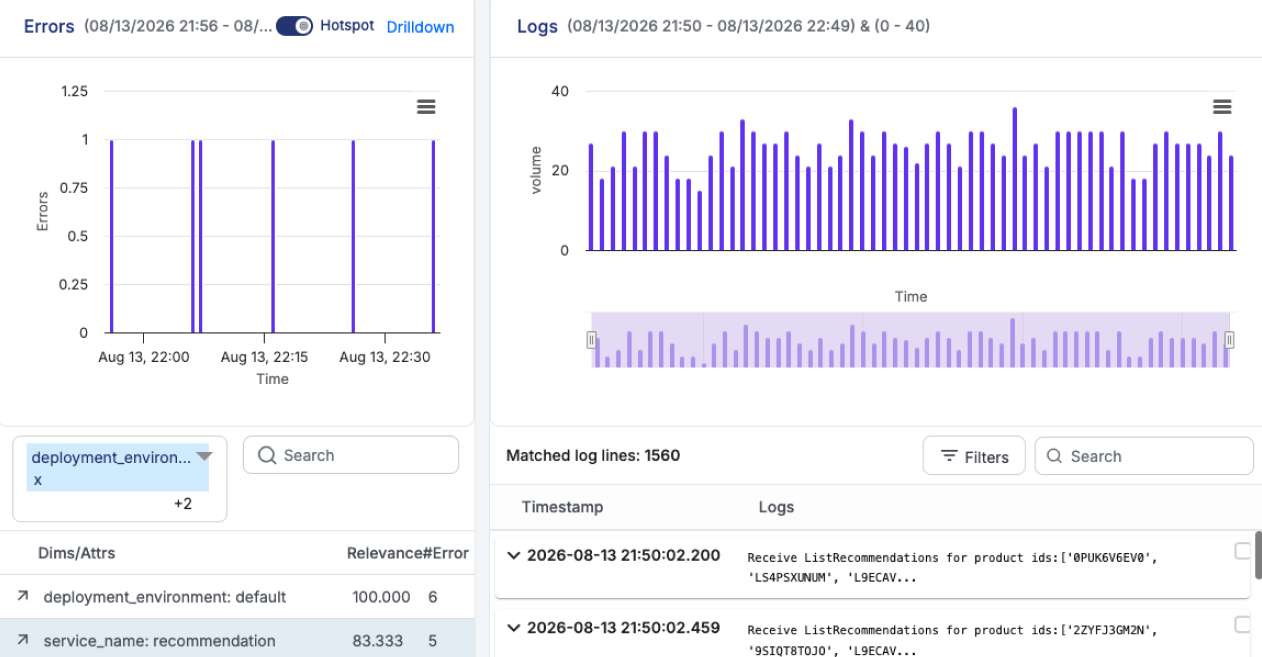
- Interactive dimensional drilldowns
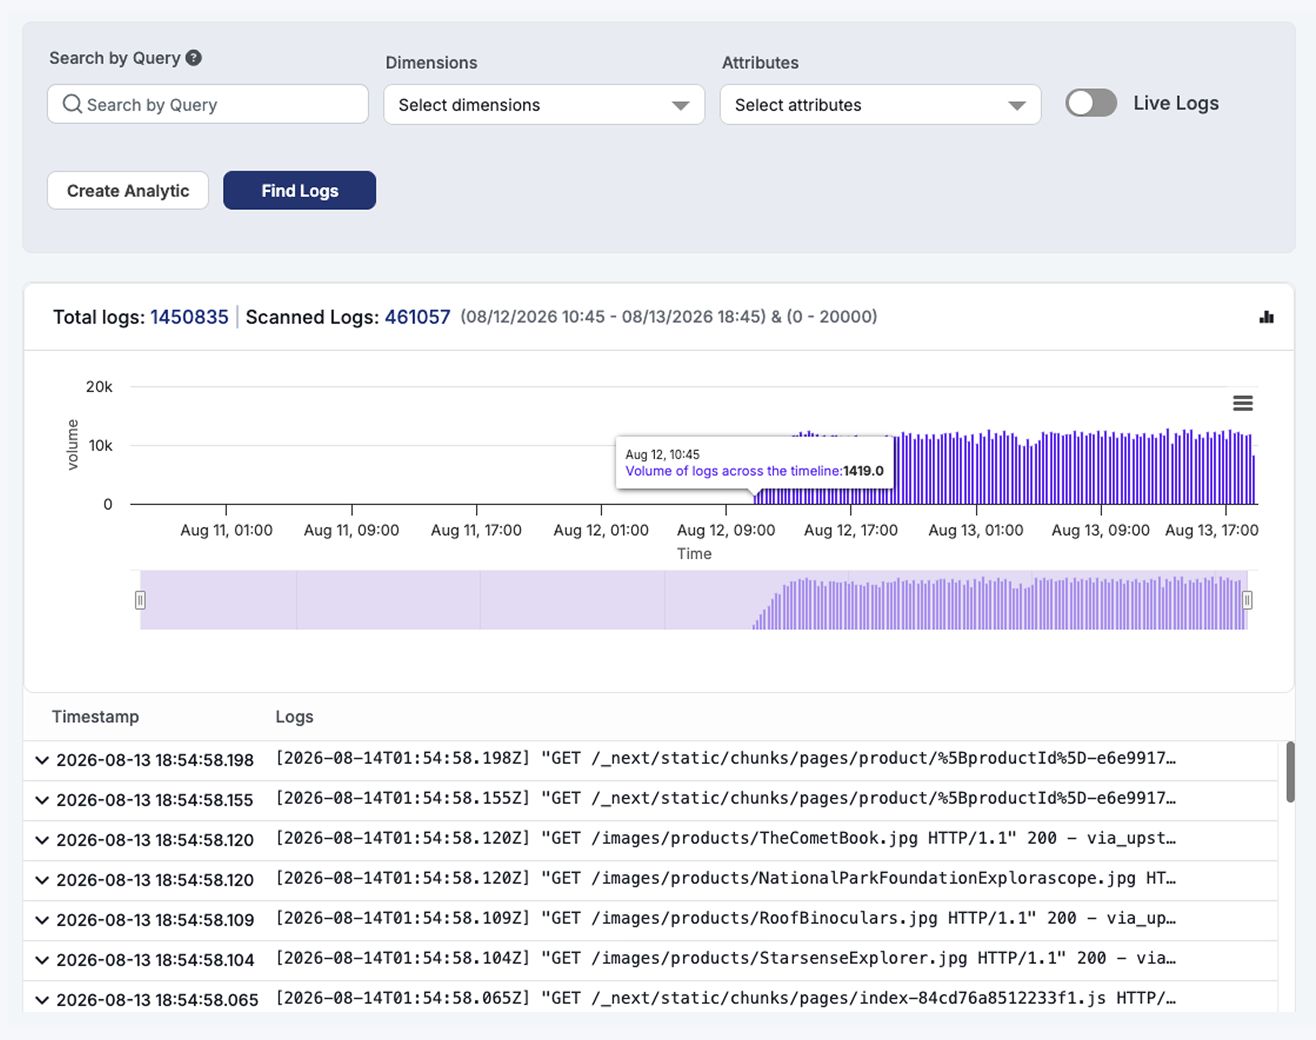
Seamlessly drills down into golden signals across any combination of dimensions to instantly isolate anomalous behavior and outliers. - Instant high-cardinality queries
Scans billions of raw logs, metrics, and trace spans instantly without indexing caps. - Smart fuzzy entity resolution
Uses intelligent algorithms to resolve variations in service naming conventions, overcoming static entity mapping limitations to surface related logs automatically.
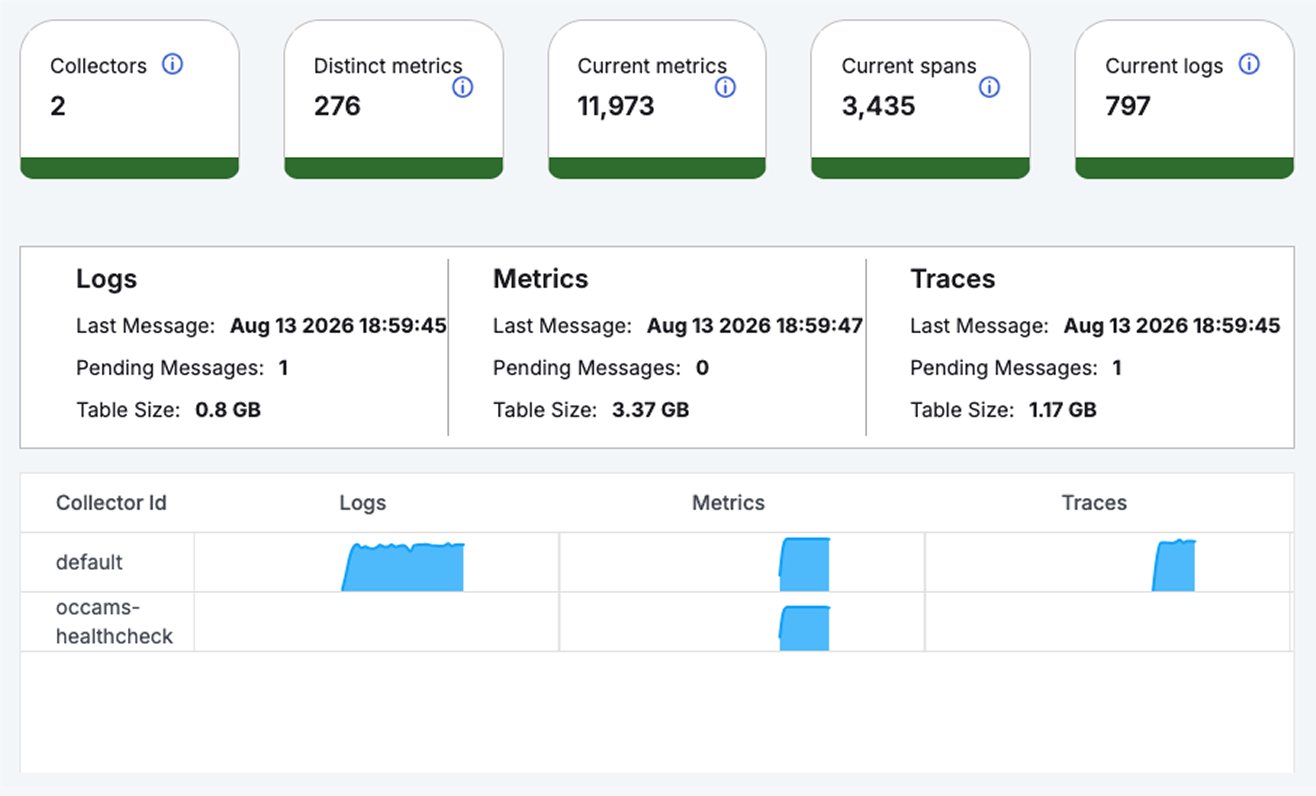
Native OpenTelemetry (OTel) pipeline
- Zero code rewrites
Point your existing OpenTelemetry collectors directly to OccamsHub in minutes. No custom SDKs, proprietary agents, or vendor lock-in. - Unified logs, metrics & traces
Ingest all three pillars of observability into a single runtime engine, eliminating data silos and disjointed monitoring tools. - Unthrottled streaming
Streams uncompressed telemetry directly to our Occams Context Engine with zero third-party API lag, rate limits, or query timeouts.
Eliminate runaway Observability/APM bills
Tag, query, and debug without watching your vendor bill explode.
- Up to 10x storage efficiency
Reduces telemetry storage using advanced columnar compression, passing the savings directly back to you. - Zero index overhead
Eliminates legacy inverted-index bloat that adds 50%+ in storage overhead, allowing you to query high-cardinality data without surprise bill spikes. - Predictable platform pricing
Replace complex host taxes, log rehydration surcharges, and dynamic metric fees with transparent, flat-rate pricing.
Custom analytics & ad-hoc SQL
- Full-text search
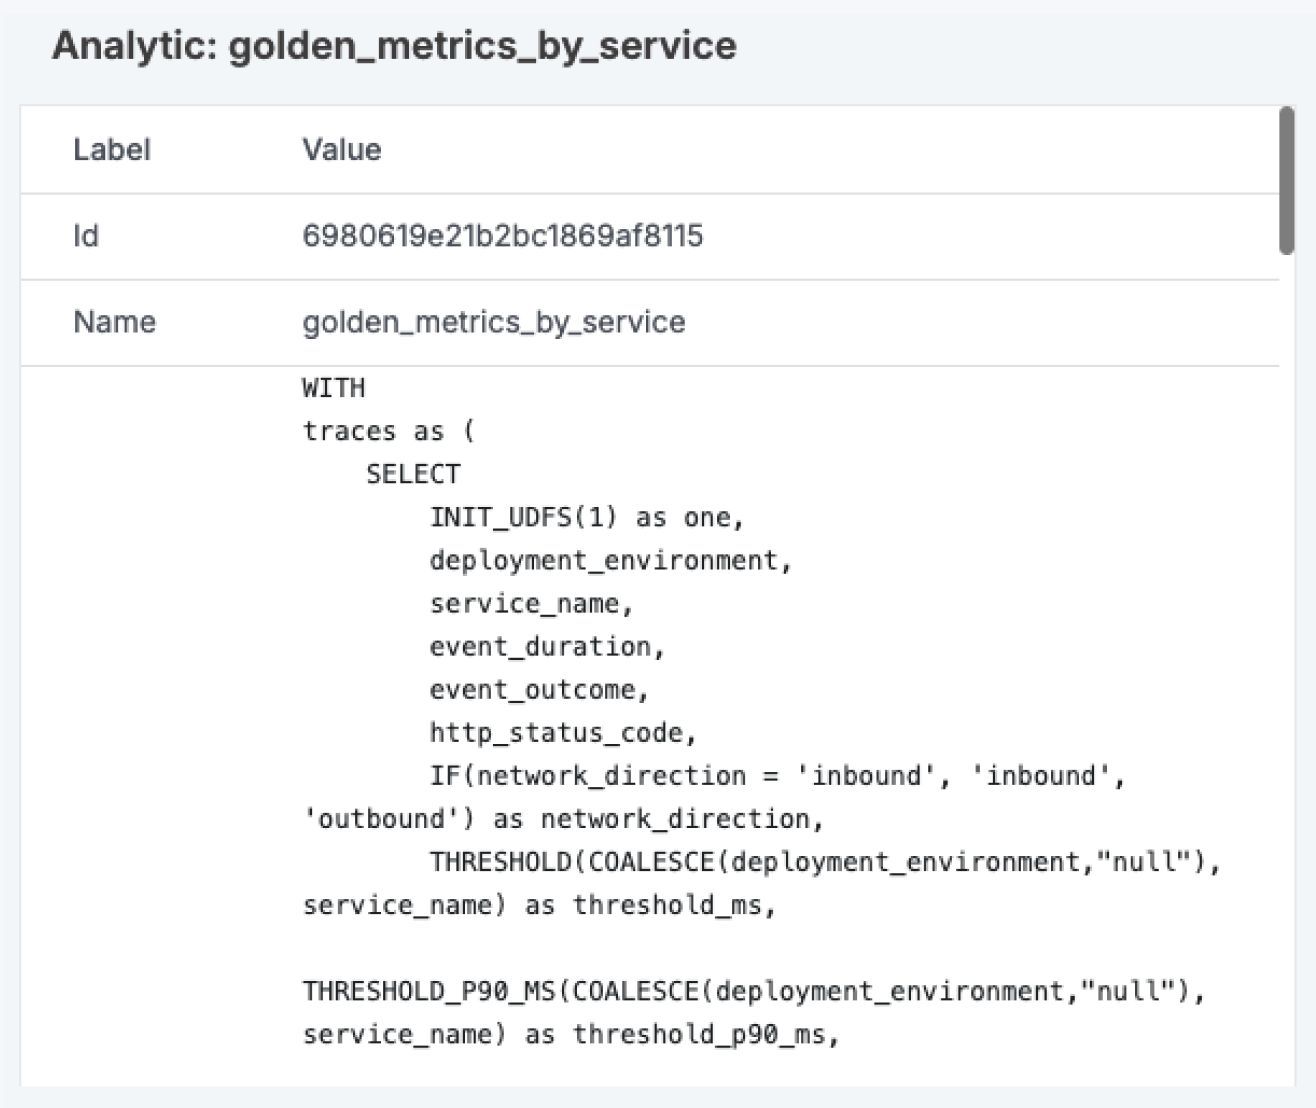
Searches logs, metrics, and traces across custom dimensions and attributes using standard Lucene query syntax without learning proprietary query languages. - Log-to-metric conversions
Computes custom metrics and statistical aggregations on raw log and trace streams using ad-hoc queries. - Bespoke analytics extensibility
Builds operational views and custom dashboards directly on top of raw runtime streams using Spark SQL without legacy APM indexing taxes or artificial query limits.
Eliminate vendor markup
Legacy APMs charge you three times: once to ingest raw noise, once to store it, and once to query it. When you hit high cardinality, inverted-index complexity explodes your bill exponentially. OccamsHub avoids this by streaming directly into a columnar OLAP core, giving access to full-fidelity, high-cardinality context without the APM markup.